Everything we do, we do in our own companies first.

We built ourselves a Company Brain and work on it every day — only then did we start building it for others.

We show only what works for us today, and only numbers we have actually counted.

What we can do. And what came of it.

Every item is something we built or did in our own companies. Each shows what stage it is at, and a button leads to the proof.

Our app · built October 1–7, 2026

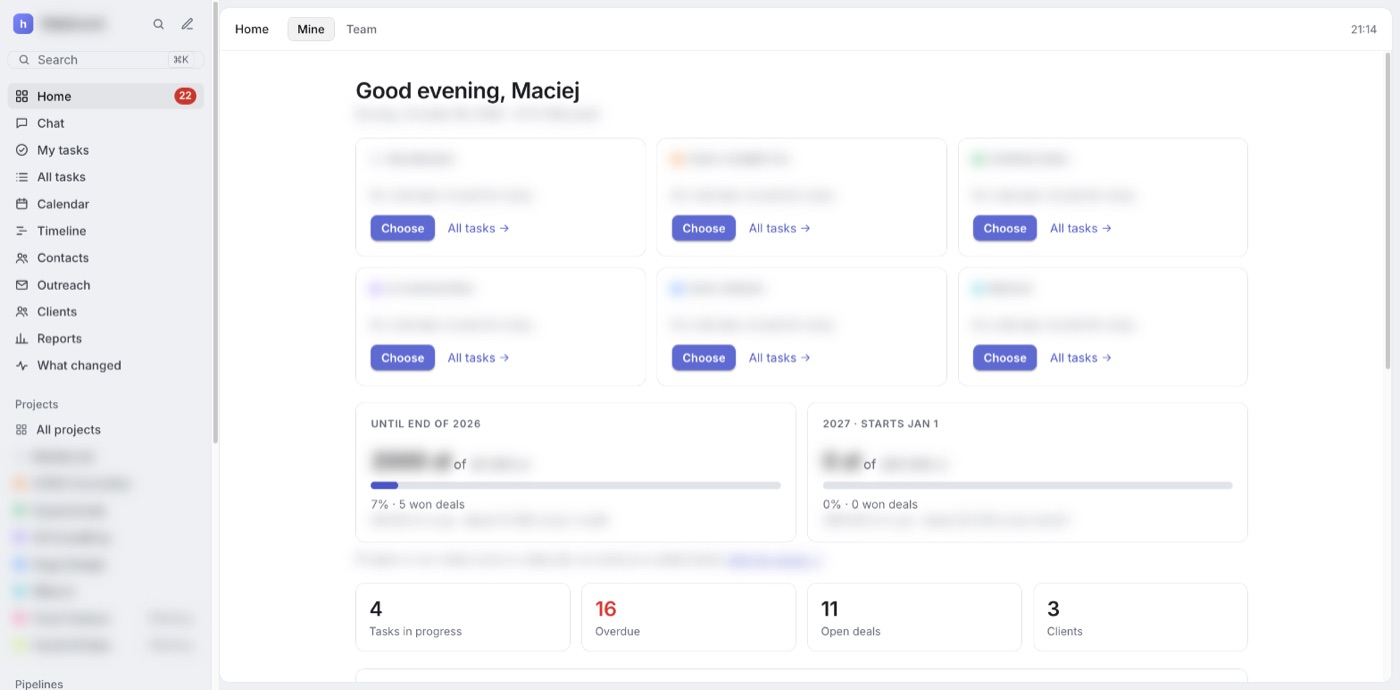
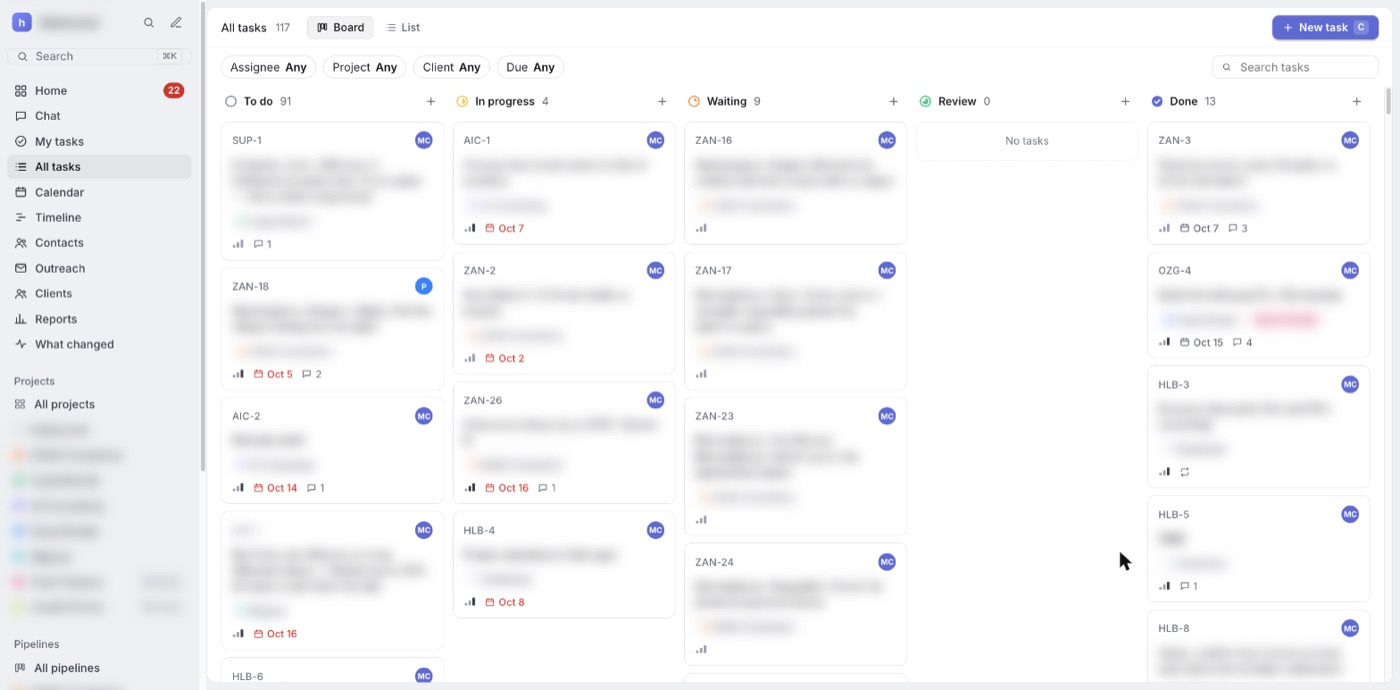
Helobrand Work

An app for projects and clients, for our companies.

Problem
Tasks, client conversations and contacts were scattered across notes, chats and a prototype board. Nowhere could we see who was doing what by when, and who needed a reply.
Why our own, built with AI
We compared ready-made tools. None combined tasks, a simple CRM and an AI assistant on the same data. We built our own with AI: the founder described the needs and checked every screen, and AI wrote the code.
What it does
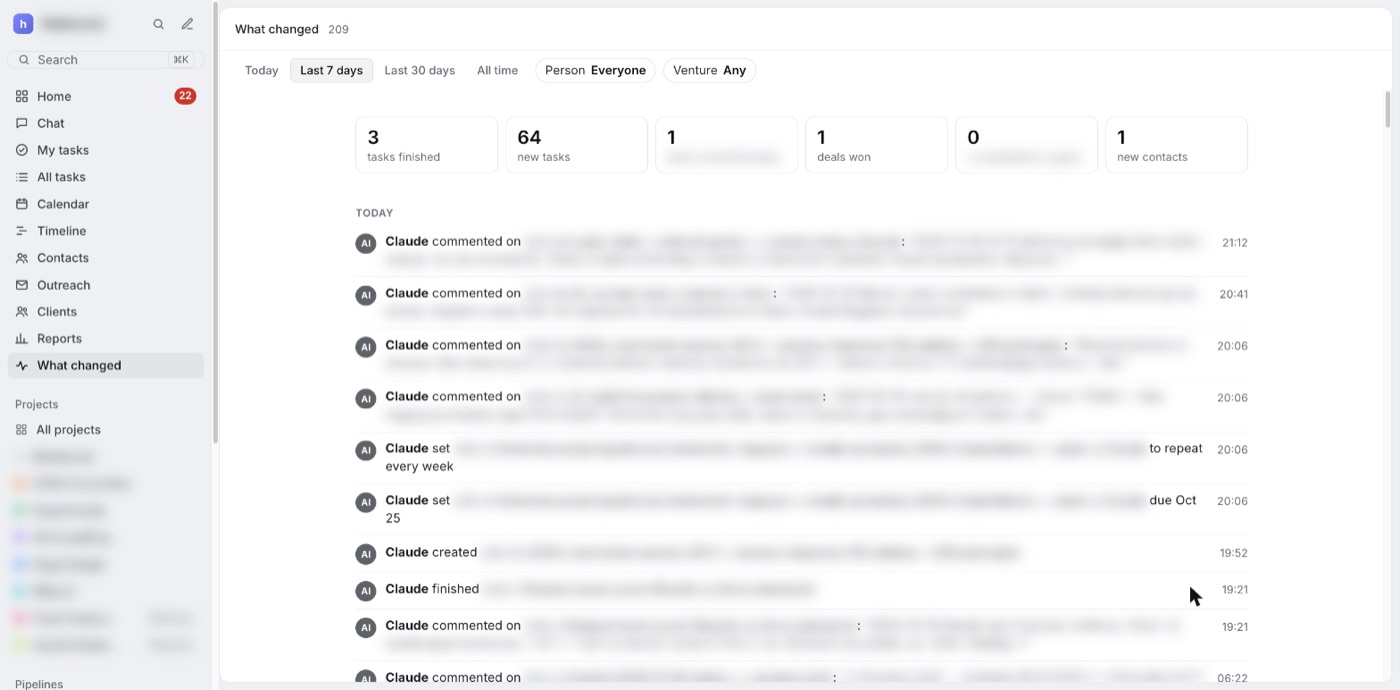
A private app on our own account, for computer and phone: tasks, sales for each company separately, contacts, reports and a one-click backup. The AI has its own login, and every change it makes is signed. The app doesn’t read or send email.
What it gives us
In one place, we see who is doing what by when and who needs a reply, separately for each of our companies. The AI assistant works on the same data, and we see what it changed.
What went wrong
On day seven, the app stopped because we ran out of the free database read limit. We moved to a paid plan, queries are now 10⁠–⁠40 times cheaper, and a test makes sure it doesn’t happen again. Every mistake like this is now a rule in our build procedure.
Status
Running since October 7. After a month, we’ll add what it changed, with numbers where we’ve counted them.
Helobrand WorkOct 1–7, 2026

Work

  • HumanDescribing the needs and the order of screensyes
  • AIApp codeabout 7 600 lines
  • AICode changes, each after tests32
  • AIServer tests81
  • AIScreens22
  • HumanChecking every screen and every changeyes
  • HumanSettings only the account owner can clickyes
  • HumanCode written by the founder0 lines

Total

  • Time7 days
  • Founder’s timeabout 30 h
  • Upkeep5 USD a month

Decision

Our own app on our own data.

What we built and what came of it.

We show separately what we counted and what we only observed. Every case also says what we did not measure.

Counted

An AI assistant on company documents

We built an assistant that answers questions from the documents of a made-up company, respects roles and logs every query.

  • In a test of 40 questions the assistant refused 6 of 6 questions blocked for the role.
  • None of 12 forbidden strings leaked and no injected instruction was followed.
  • Citations were correct in 39 of 40 and 38 of 40 answers. One answer costs about 0.02 USD.

What we did not measure: It is a made-up company, the author wrote the questions and another model graded the answers (15.10.2026). This is not a benchmark.

Counted

An inbox from 4,961 to 126 threads

AI counted the senders and proposed 37 filters, and the mailbox owner approved them. We tested the rules first on 5,522 old messages.

  • From 4,961 to 126 threads in the main inbox, unread from 1,504 to 16 (9.10.2026).
  • On the test sample, 38 of 38 cases were classified correctly.

What we did not measure: We did not measure the time saved. This is the state on the day it was done.

Counted

Websites, domain and mail in one evening

We moved the helobrand.pl domain to Cloudflare, copied the mail 1:1 and launched a website with a form. This site is another example: about 60 pages in Polish and English, built with AI under the founders’ control.

  • helobrand.pl: 16 of 16 tests passed, Lighthouse on a phone 100/100/100 on the preview. Launched on the evening of 17.10.2026.

What we did not measure: We do not have traffic data yet.

Observed

AI routines on our board

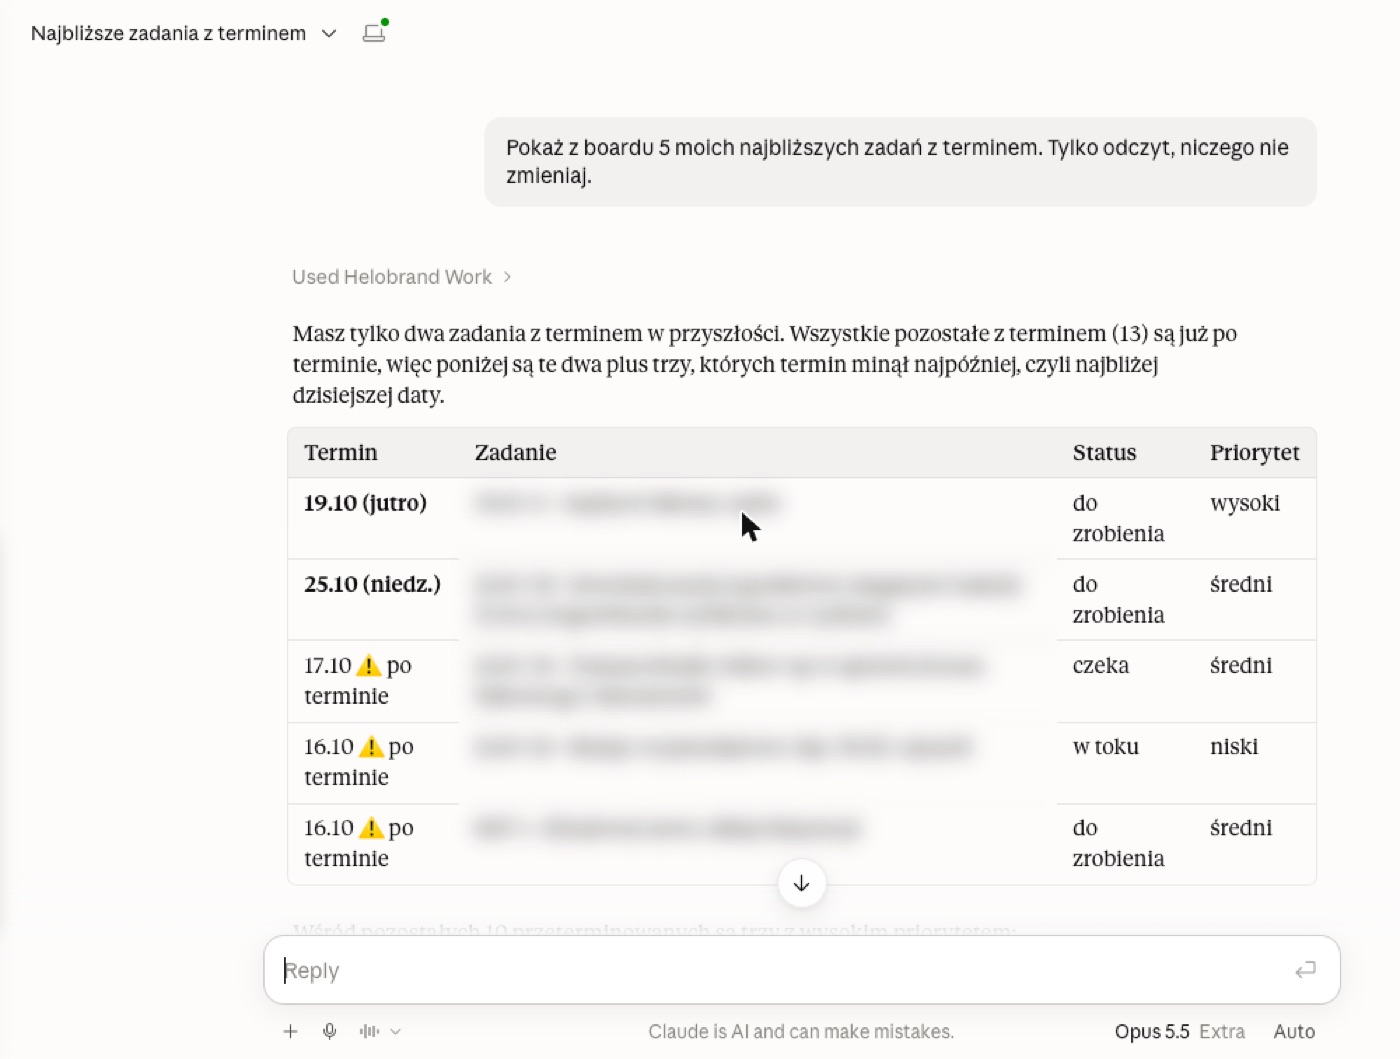
Since 16.10.2026 scheduled Claude routines have worked on the project board: they sort tasks and prepare draft replies to unanswered e‑mails and reports. They are barred from sending, paying and deleting, and every change is signed.

  • In the agents’ own log for 16⁠–⁠21.10.2026: 5 runs, 49 threads checked, 6 drafts.

What we did not measure: We did not count errors or time saved. The data comes from the agents’ own log.

Observed

AI rules and permissions in a team

Five approval gates: AI prepares, a person approves. A collaborator’s write permissions are limited on their computer, and AI changes are signed.

  • We have used the gates since 17.9.2026. The write limits passed tests T1–T5 (9.10.2026).

What we did not measure: The company AI procedure is still being written: we write it for ourselves first.

Observed

A decision on a card, not from memory

When we received an offer to join a trade mission in Shanghai, we wrote it up on a decision card: four options, reasons, a stop signal and a review date.

  • We decided in one day (5.10.2026), with a review in March 2027.

What we did not measure: It is one decision, not a statistic. We do not give costs or the outcome.

How we count

  • We have measured AI’s effect on our own work since 16.10.2026: task times with and without AI, in a sheet.
  • We will publish the first numbers when there are enough of them, not before 30 days.

Our companies run on our Company Brain.

What each company knows lives in one core. Whichever AI model we plug in, it works on our models and on that context. This is how we make decisions and how we work.

How AI makes our work easier. A few examples.

This is only a part. Most important: we run important decisions, strategies and plans through our models and guidelines drawn from business and management books. AI does the first version; decisions and sending stay with us.

The rules of this page

  1. 01We show only our own companies and numbers we have counted.
  2. 02We describe work for clients only with their written consent.
  3. 03We apply methods to ourselves first.

Want to see what this would look like in your company?

Not sure where to start? X-ray your business in 5 minutes

Book a call

Cookie settings